Spark vs Hive SQL: Why Choose Spark for Big Data Processing?
Using Spark instead of Hive SQL for big data processing offers several advantages:
-
Processing Speed: Spark is an in-memory computing framework, allowing for faster computation compared to Hive SQL, which relies on Hadoop MapReduce.
-
Data Processing Capabilities: Spark provides a rich set of APIs and features enabling complex data manipulation and analysis. While Hive SQL can perform data processing, its capabilities are relatively limited.
-
Data Storage: Spark can connect to various data sources, including Hive, HBase, and Cassandra, while Hive SQL is restricted to data storage within the Hadoop ecosystem.
-
Programming Languages: Spark supports multiple programming languages like Scala, Java, and Python, offering more flexibility for complex data processing tasks than Hive SQL's SQL-only support.
-
Scalability: Spark can be extended with plugins, making it highly scalable. Hive SQL's scalability is relatively limited.
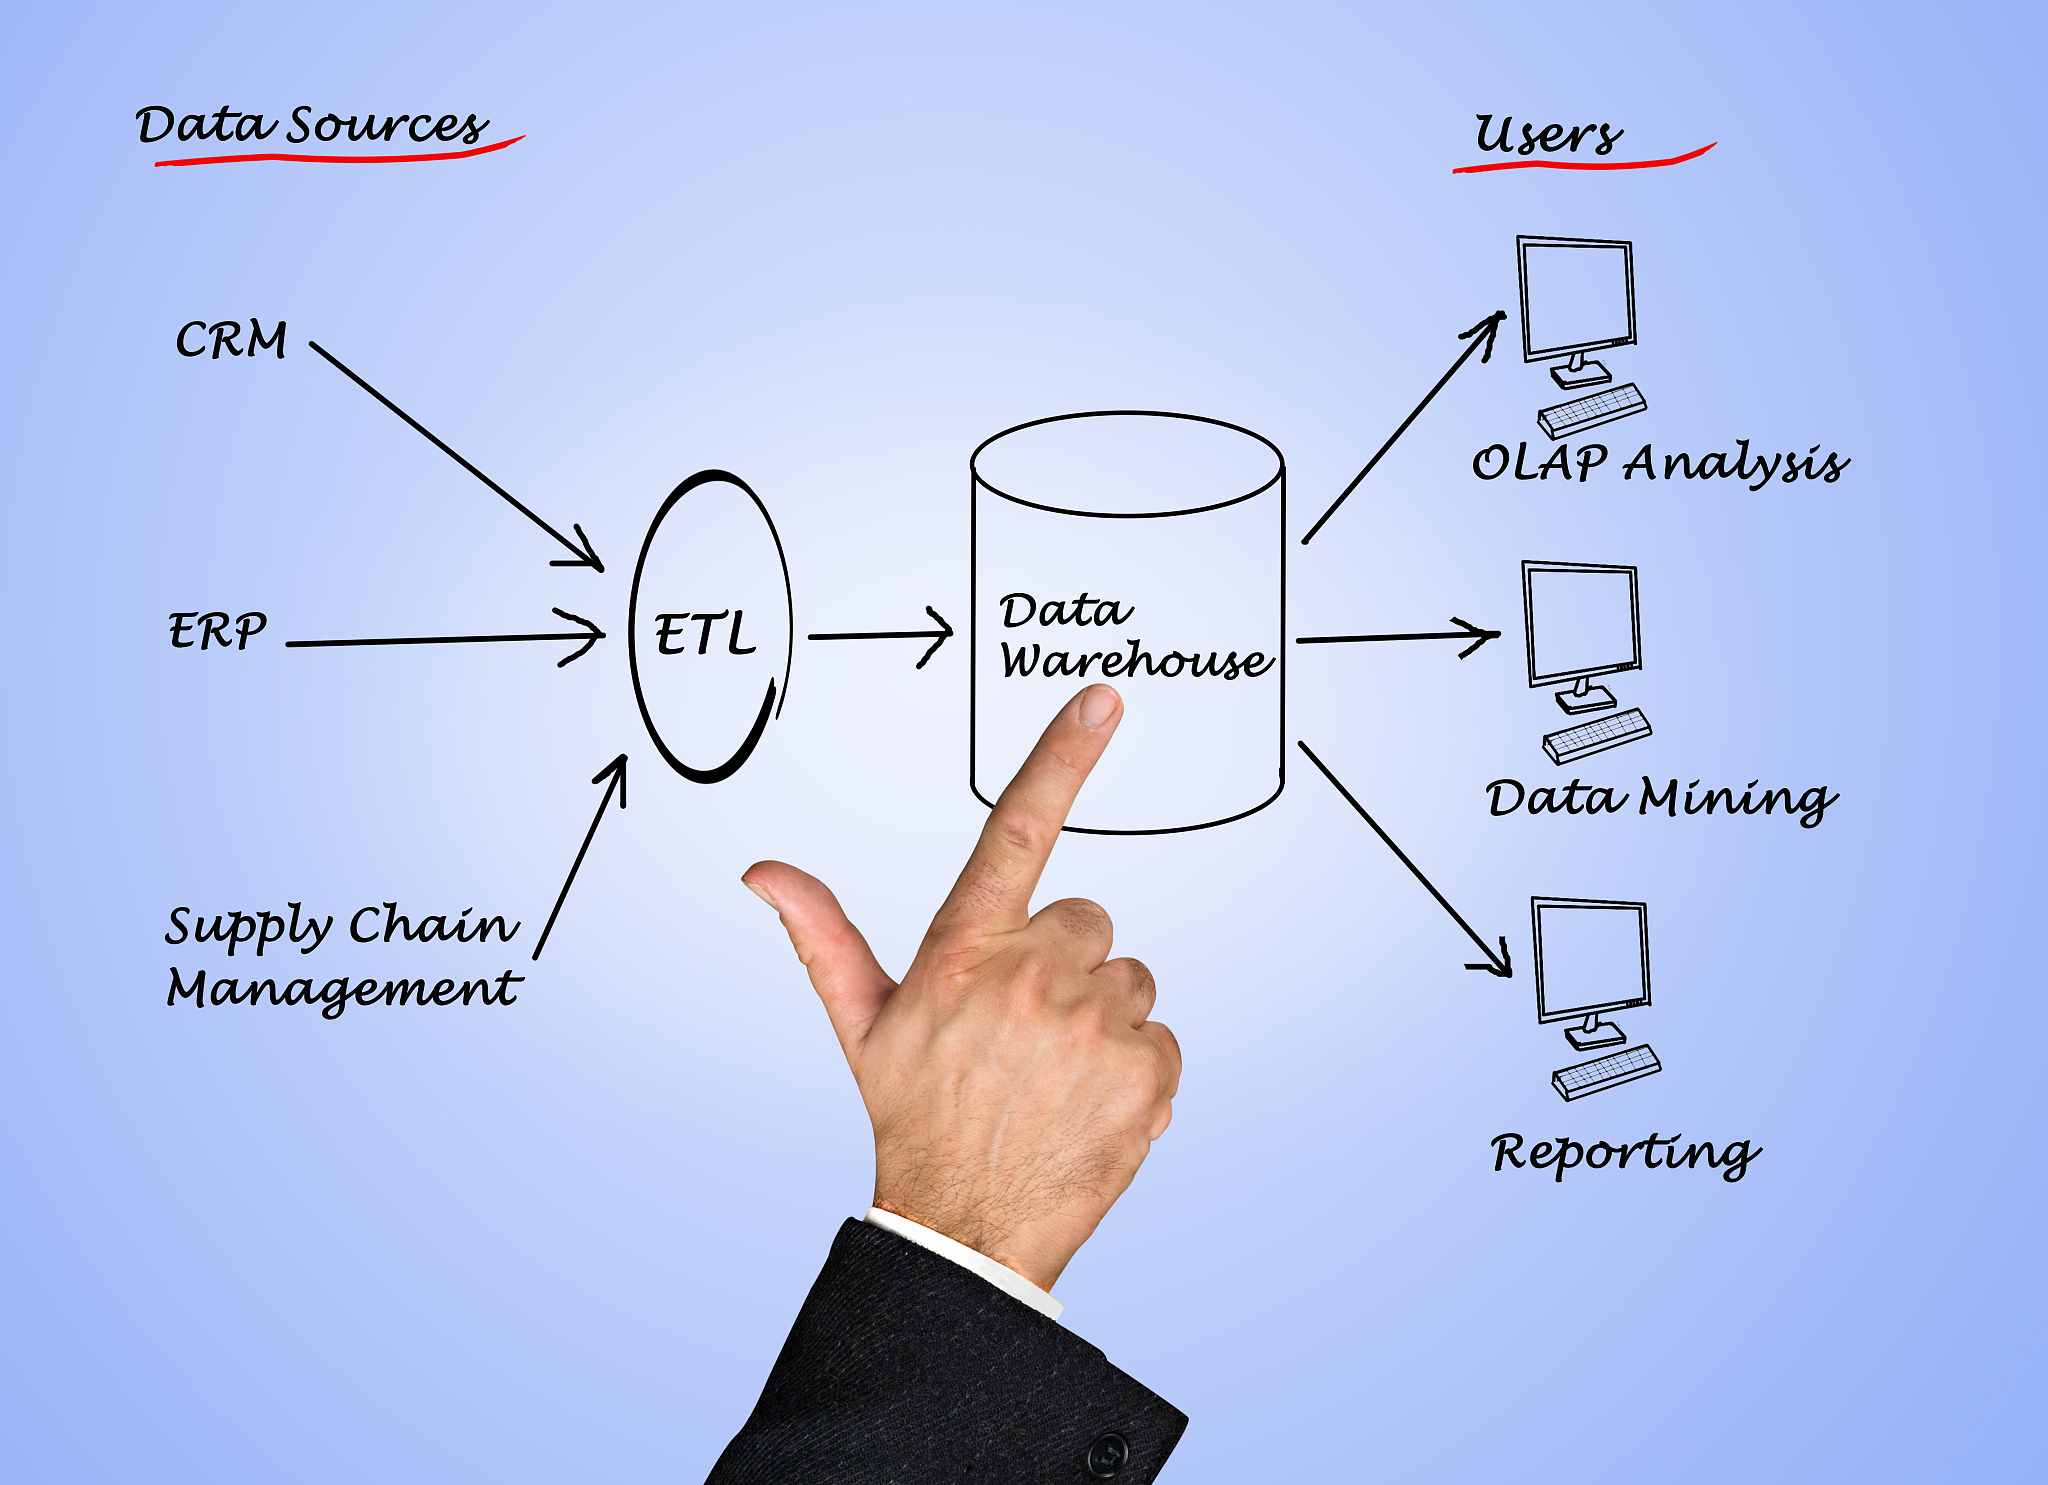
Ultimately, Spark is better suited for big data processing and analysis, while Hive SQL is more appropriate for data warehouse construction and management. The choice depends on the specific business needs and data processing tasks at hand.
原文地址: https://www.cveoy.top/t/topic/mXpg 著作权归作者所有。请勿转载和采集!